

TinyLLaVA: A Framework of Small-scale Large Multimodal Models

Baichuan Zhou
bczhou
AI & ML interests
Computer Vision
Organizations


models 8
bczhou/tiny-llava-v1-hf
Image-Text-to-Text • 1B • Updated • 2.57k • 57
bczhou/TinyLLaVA-2.0B
Image-Text-to-Text • 2B • Updated • 47 • 6
bczhou/TinyLLaVA-1.5B
Image-Text-to-Text • 2B • Updated • 177 • 20
bczhou/TinyLLaVA-3.1B-Pretrain
Text Generation • 3B • Updated • 18
bczhou/TinyLLaVA-3.1B
Text Generation • 3B • Updated • 100 • 27
bczhou/TinyLLaVA-2.0B-SigLIP
0.4B • Updated • 22 • 2
bczhou/TinyLLaVA-1.5B-SigLIP
0.4B • Updated • 137 • 1
bczhou/TinyLLaVA-3.1B-SigLIP
0.4B • Updated • 26 • 4
datasets 7
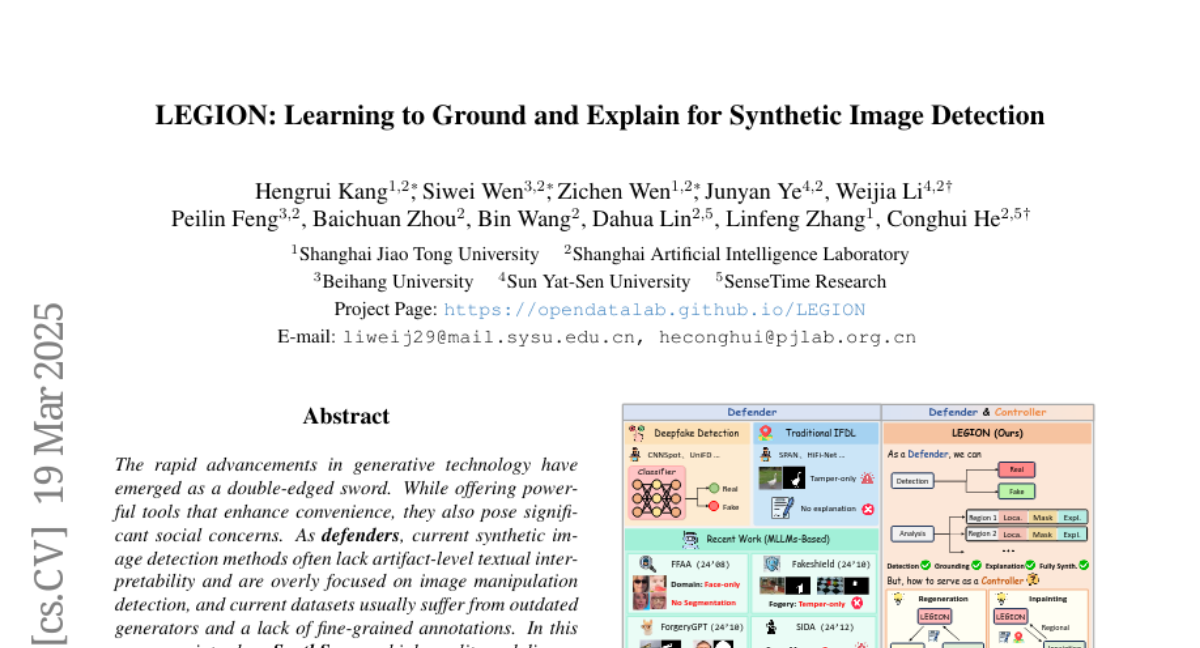
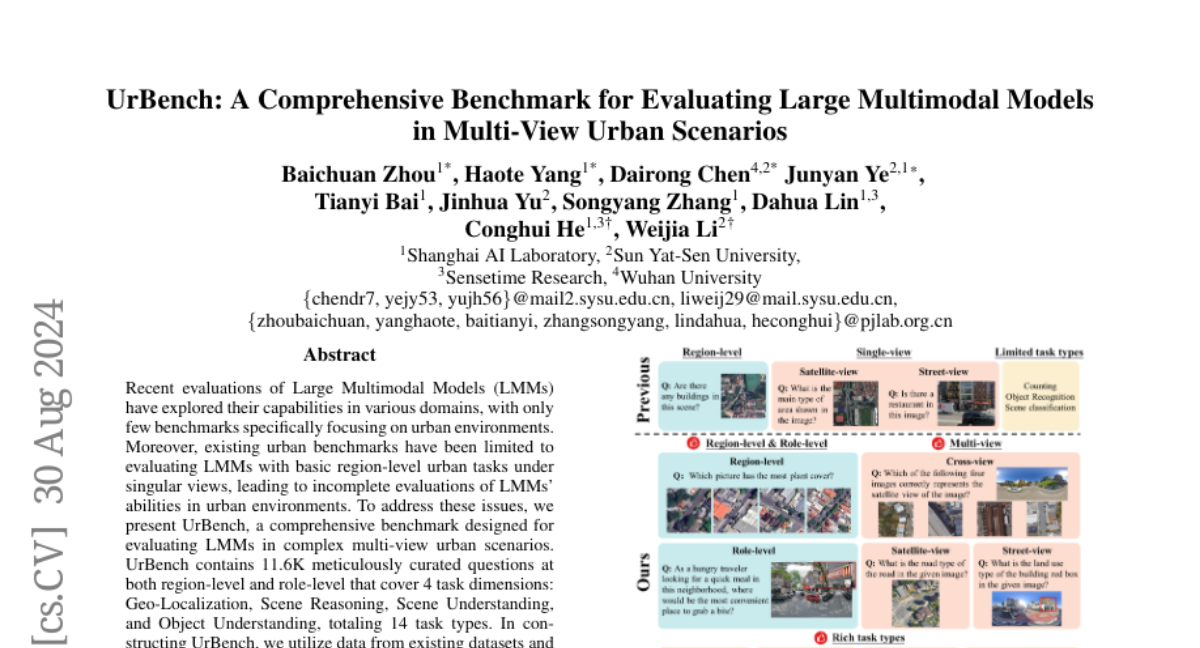
bczhou/UrBench
Viewer • Updated • 11.6k • 301 • 5
bczhou/LOKI
Preview • Updated • 283 • 6
bczhou/CityBench-SubTasks
Viewer • Updated • 12.8k • 177
bczhou/SyntheticBench-Videos
Viewer • Updated • 264 • 28
bczhou/CityBench-v0.3
Viewer • Updated • 9.71k • 48
bczhou/CityBench-v0.2
Viewer • Updated • 9.71k • 39
bczhou/CityVQA-v0.2
Viewer • Updated • 2.5k • 41 • 1