

Real In, Real Out: What If We Only Use Real Data for Scene Text Editing?
Paper • 2610.27592 • Published • 27
Official model checkpoint for Real In, Real Out: What If We Only Use Real Data for Scene Text Editing? (NeurIPS 2026).
Xingsong Ye, Yongkun Du, Jiaxin Zhang, Chong Sun, and Zhineng Chen
HF Paper · arXiv · NeurIPS 2026 · Code · Model · Demo · TextRIRO-3M · RIROCommon
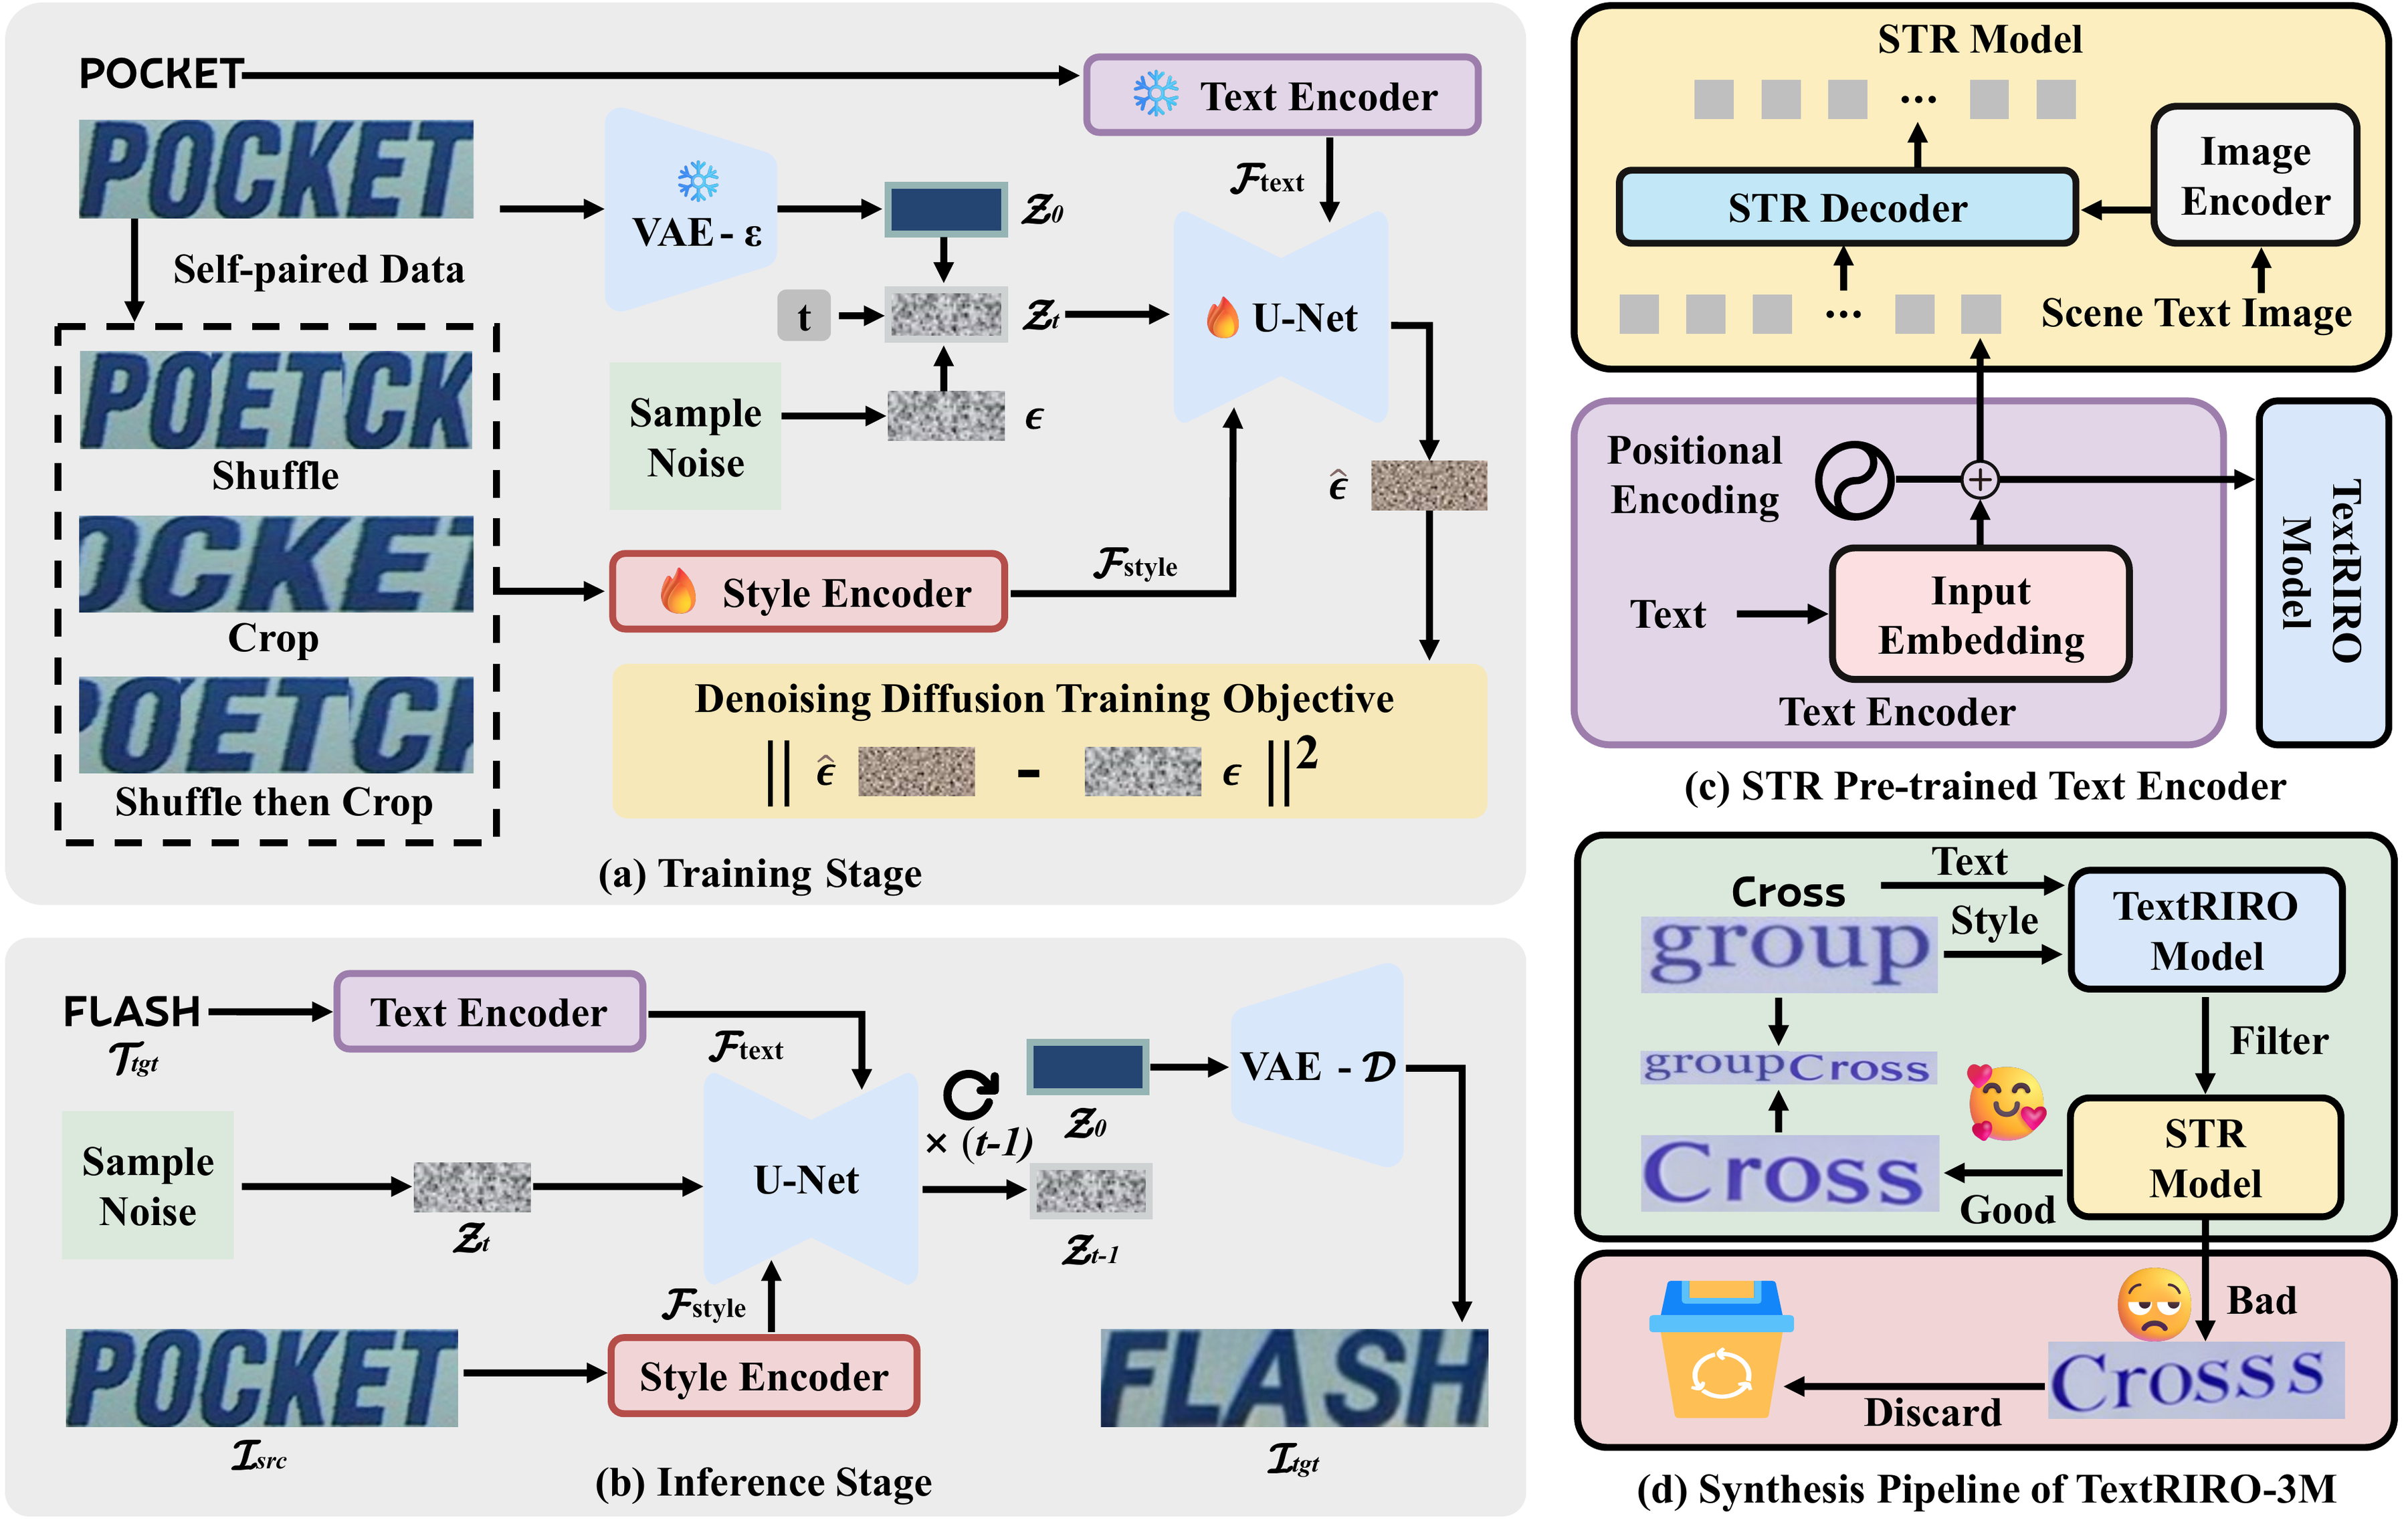
TextRIRO uses conditional diffusion to replace text in a scene-text crop while preserving the reference appearance. Shuffle&Crop creates self-paired supervision by disrupting text semantics in real images while retaining style cues. A multi-scale style encoder and an STR-pretrained text encoder condition generation on appearance and target characters. Training requires no synthetic before-and-after editing pairs or character segmentation.
Here, real-only training refers to editing supervision and STR-based text-encoder pre-training. The generative backbone uses pretrained Stable Diffusion components.
| Item | Details |
|---|---|
| Released weights | textriro.pth |
| Inputs | A cropped scene-text image and the desired replacement text |
| Output | An edited crop with the requested text |
| Backbone components | Stable Diffusion 1.5 U-Net and scheduler; Stable Diffusion 2.1 VAE |
| Text conditioning | STR-pretrained character embeddings provided in the code repository |
| Generation resolution | 64 × 256 pixels; the inference script restores the source dimensions |
| Training data | U14M-Filter, the filtered real-image subset of Union14M, distributed through OpenOCR-Data |
This repository distributes a PyTorch checkpoint for the project's custom implementation. Use the loading and inference scripts in the code repository.
git clone https://github.com/YesianRohn/TextRIRO.git
cd TextRIRO
Follow the repository's installation and checkpoint preparation instructions. The inference script requires CUDA. Prepare the SD 1.5 U-Net/scheduler, SD 2.1 VAE, and STR-pretrained text encoder at the paths specified in configs/train.yaml.
Run this from the cloned repository root:
from huggingface_hub import hf_hub_download

hf_hub_download(
    repo_id="Yesianrohn/TextRIRO",
    filename="textriro.pth",
    local_dir=".",
)
Put source crops in example/i_s/. Create example/i_t.txt with one image filename and replacement string per line:
sample_001.png FLASH
sample_002.jpg Real In Real Out
Separate the filename and target with one space. Spaces inside the target are supported. Every source image must have a matching entry.
python inference.py \
  --ckpt_path textriro.pth \
  --dataset_dir example \
  --output_dir example_result \
  --num_inference_steps 20 \
  --guidance_scale 2.2 \
  --seed 42
Outputs are written to example_result/ using the source filenames. To try the model interactively, visit the online demo.
EN_symbol_dict.txt plus the space character. The release should not be treated as a general multilingual editor.If you use TextRIRO in your research, please cite:
@inproceedings{ye2026textriro,
  title     = {Real In, Real Out: What If We Only Use Real Data for Scene Text Editing?},
  author    = {Ye, Xingsong and Du, Yongkun and Zhang, Jiaxin and Sun, Chong and Chen, Zhineng},
  booktitle = {Advances in Neural Information Processing Systems},
  year      = {2026},
  url       = {https://neurips.cc/virtual/2026/loc/sydney/poster/153296}
}
Base model
stable-diffusion-v1-5/stable-diffusion-v1-5