Hugging Face
Models
Datasets
Spaces
Buckets
new
Docs
Enterprise
Pricing
Website
Tasks
HuggingChat
Collections
Languages
Organizations
Community
Blog
Posts
Daily Papers
Hardware
Learn
Discord
Forum
GitHub
Solutions
Team & Enterprise
Hugging Face PRO
Enterprise Support
Inference Providers
Inference Endpoints
Storage Buckets
Log In
Sign Up
Jianhao Yan
Elliott
8
22
3
Follow
dark-pen's profile picture
4Rcom's profile picture
Spico's profile picture
9 followers
·
1 following
ElliottYan
AI & ML interests
None yet
Recent Activity
upvoted
a
paper
about 1 hour ago
TPPO: Tracking-Value PPO For Language Model Reasoning
upvoted
a
paper
6 days ago
Gains and Collapse in On-Policy Distillation:A Reinforcement Learning Perspective
upvoted
a
paper
27 days ago
Rethinking Critic Learning in PPO: Understanding and Mitigating Value Flattening
View all activity
Organizations
None yet
Elliott
's papers
3
arxiv:
2601.11037
arxiv:
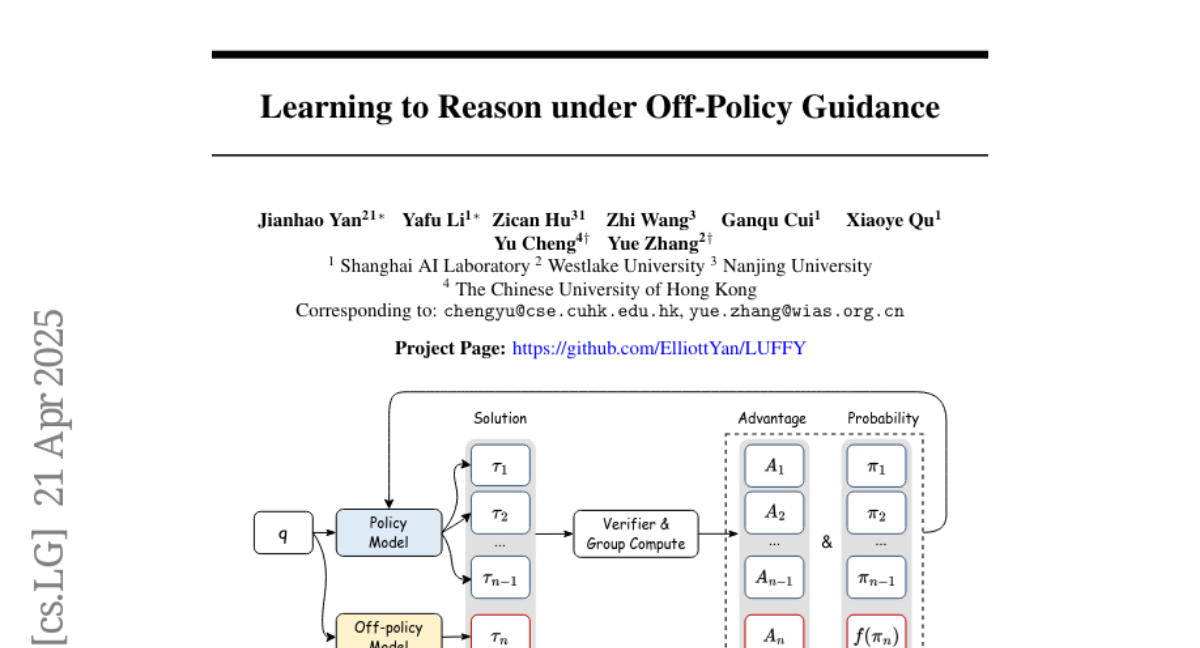
2504.14945
arxiv:
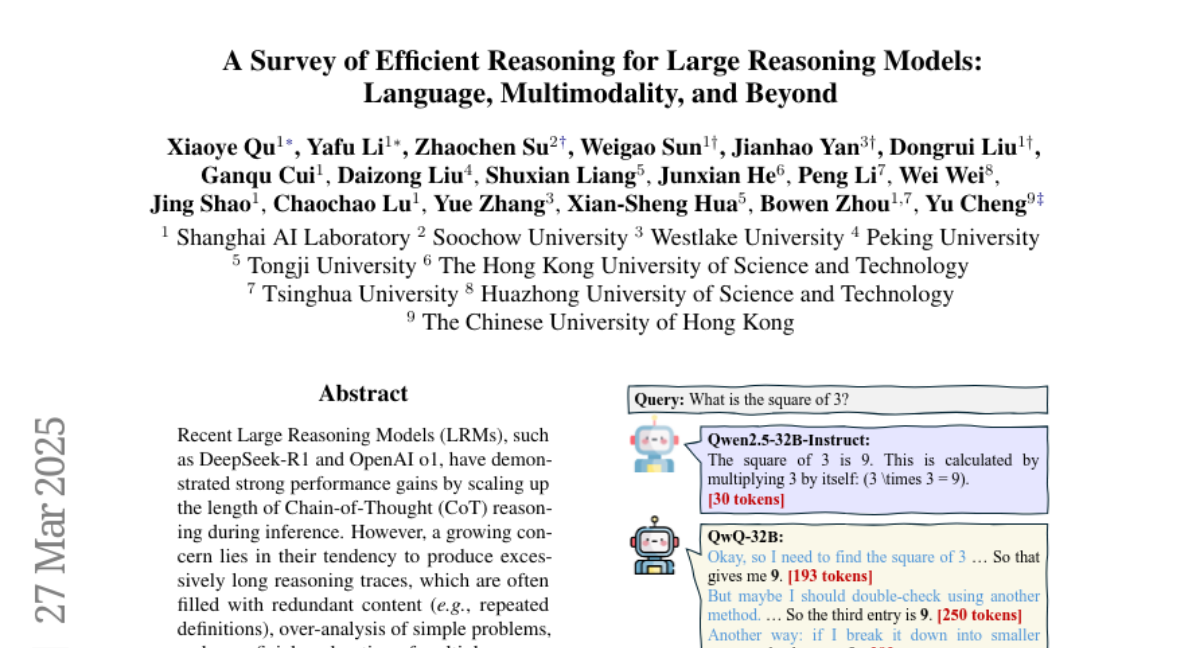
2503.21614